Home › Scan client for SAP S/4HANA®
 CaRD Scan Client
A document that is merely digitised is an image in a folder. Only the assignment makes it findable again. The CaRD Scan Client does both in one pass — split the stack, identify the document, file it on the SAP S/4HANA® object — from the scanner just as well as from PDFs you already have. Without SAP skills at the workstation.

Files into SAP S/4HANA® — private cloud, public cloud, RISE and on-premise. Additionally straight into SharePoint, Azure Blob Storage or a CMIS repository.
Delivery notes, freight papers, signed contracts, inspection reports: plenty still arrives on paper. Anyone who merely scans it into a folder has moved the problem rather than solved it.
“Scan_0043.pdf” tells nobody anything. Whoever looks for it later opens file after file — or gives up and requests it from the supplier again.
Without automatic splitting, every stack is scanned individually or cut apart afterwards. Both cost time that was not budgeted when the scanner was bought.
Paper in a binder, a scan on a drive, perhaps a mail with the same content. In an audit the problem is not the quantity but the question of which version counts.
The user loads the stack and starts the scan — on any TWAIN scanner, from a desktop device to a departmental machine with a feeder. Or they open a PDF created elsewhere: on the multifunction device, in a collection folder on a network drive, from an email. A scanner at the workstation is therefore not a prerequisite. Settings such as resolution, duplex and colour live in the profile, not in the user’s head.
Barcodes on separator sheets or on the documents themselves split the stack into individual documents automatically. One pass through the scanner becomes many documents — with nobody sorting sheets in between.
The barcode supplies the document number along the way. Where there is none, the client reads the document by text recognition (OCR) — with an AI model behind it if wanted — or the user picks the SAP object in a plain form. Either way without SAP skills and without a SAP logon at the workstation.
The finished document goes to its destination: to the SAP object, through your archive — or, without any SAP, straight into SharePoint, Azure Blob Storage or a CMIS repository. The destination lives in the profile. Visible to everyone who opens the process; the paper has done its job.
Separator sheets or codes on the document split the stack and supply the reference to the SAP object at the same time. Which codes apply and how they are structured lives in the profile — in-house number ranges included.
Processing time per page stays constant instead of growing with the stack. A 400-page run therefore behaves predictably — which decides whether the morning post gets through.
Resolution, duplex, colour, target object, barcode patterns: everything lives in the profile. Users pick their profile and get going — there is nothing to configure and therefore nothing to configure wrongly.
Because no SAP skills are needed at the scanning station, the department does not have to do the digitising. The document is already assigned by the time it arrives there — and nobody waits for a colleague with SAP access.
The SAP connection is switchable. If one route stumbles on a PC with its local SAP installation, the other takes over — instead of a workstation standing still for days.
The client files into your existing SAP archive. It can just as well write straight into SharePoint, Azure Blob Storage or a CMIS repository — with no SAP in between. With the CaRD Connector the same store doubles as your SAP archive.
SAP S/4HANA® is the primary destination — in every deployment model. The same client additionally brings documents straight into SharePoint, an Azure storage account or a CMIS archive: same interface, same profiles, same barcode splitting, only the destination in the profile differs. And anyone without SAP uses it just the same.
On the business object — purchase order, invoice, supplier, order — through your SAP archive or the CaRD Connector. In every deployment model, from on-premise to public cloud.
Scan to SharePoint: the document lands directly in the library, no detour. With the CaRD Connector the same library doubles as your SAP archive — one store, not two.
Straight into the storage account — as inexpensive storage for scanned holdings. Searching it without a connector: the CaRD Workspace for Azure.
Any archive that speaks the open CMIS standard — the CaRD Connector as well as an existing DMS with a CMIS interface. Browser access: the CaRD Workspace for CMIS.
 In action
At the top the toolbar: scan, open file, simulation, save, the scan profile and the language selector. On the left the scanner source and resolution, on the right the tools for rotating, cropping and zooming, plus the action log and barcode summary. That is all the scanning station needs.
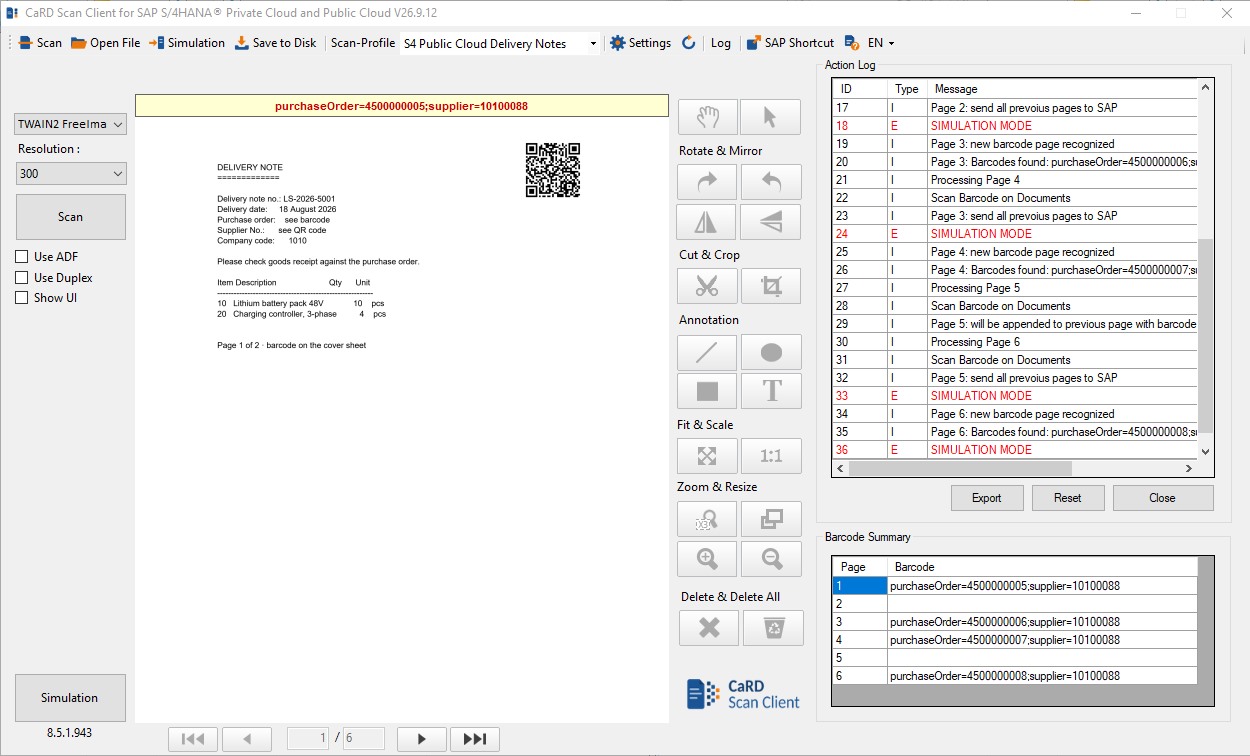
Scanner, barcodes, SAP connection, archive, text recognition, AI model and language — every setting lives in a profile the administrator sets up once. At the scanning station you only pick the profile. And anyone who does want to look something up finds the manual inside the program.


Yes. Besides filing on the SAP object, the client can write straight into SharePoint, Azure Blob Storage or a CMIS repository — with no SAP system in between. Interface, profiles and barcode splitting are the same; only the destination in the profile differs. That makes it a scan client for SharePoint or for a CMIS archive as well, entirely independent of SAP.
No. The client also processes PDFs created elsewhere — on the department’s multifunction device, in a collection folder on a network drive or from an email. “Open file” instead of “Scan”, the rest is the same: split, recognise, file on the SAP object. That also covers a backlog that was scanned long ago but never assigned.
Yes. Besides barcodes the client reads documents by text recognition (OCR) — and can use AI models for it: models from Anthropic or OpenAI, from other providers, or a locally operated model that never leaves your premises. Which model does the work is configuration, not a rebuild. The barcode remains the fastest and most unambiguous route; OCR and AI take over where there is none.
English, German, French, Dutch, Spanish and Italian — switchable right in the toolbar or automatically by system language. Every field carries a hint in the chosen language. Further languages are a language file, not a new client.
SAP S/4HANA Public Cloud and private cloud as well as RISE with SAP and S/4HANA on-premise. The scanning station stays the same in every deployment model: load the stack, scan, assign — what differs is only the route by which the document then reaches the SAP object.
No. The scan client is a standalone application with a plain interface — load the stack, scan, assign. Anyone working with barcodes does not even have to pick anything. That is precisely why the mail room can do the scanning instead of the department.
Every device with a TWAIN driver — from a small desktop scanner to a departmental machine with feeder and duplex. So you are not tied to a brand and can keep using the devices you have.
The client reads barcodes on separator sheets or directly on the document and splits the stack accordingly. The code produces the reference to the SAP object. Which codes apply and how they are structured lives in the profile — so in-house number ranges can be mapped cleanly as well.
Yes, and that is not a footnote: multi-page stacks are built so that processing time per page stays constant. A 400-page stack therefore does not slow down disproportionately compared with a 40-page one — which is exactly where simple tools fail in daily operation.
In most organisations the mail room or a central capture team — precisely because no SAP skills are needed at the scanning station. The department is not burdened in the first place, and documents are already assigned by the time they arrive there.
Wherever the profile says: on the SAP object in your archive — with common SAP archive systems as well as with the CaRD Connector for SharePoint, Azure Blob Storage, Amazon S3, STACKIT or a file system. Or, without SAP, directly in SharePoint, in Azure Blob Storage or in a CMIS repository.
That depends on the deployment model, and both routes are built in. Against S/4HANA on-premise, private cloud and RISE with SAP the connection runs through the SAP connection library — optionally by two routes, switchable via a setting. That sounds like a detail, but in daily use it is the difference between “it works” and “it does not work on this one PC”: where one route stumbles over the local SAP installation, the other steps in. Against S/4HANA Public Cloud the client files through OData — the released SAP standard attachment service, with no modification and no custom program in the core system. Nobody notices any of this at the scanning station: the interface is the same in every deployment model.
We quote per customer — by workstations and the scope you need. Request an individual quote; we are happy to show you a no-obligation live demo first.
Tell us how many documents arrive on paper each day and which SAP objects they should hang on.
